MYRTUS Cognitive Engine
The three MYRTUS technology pillars
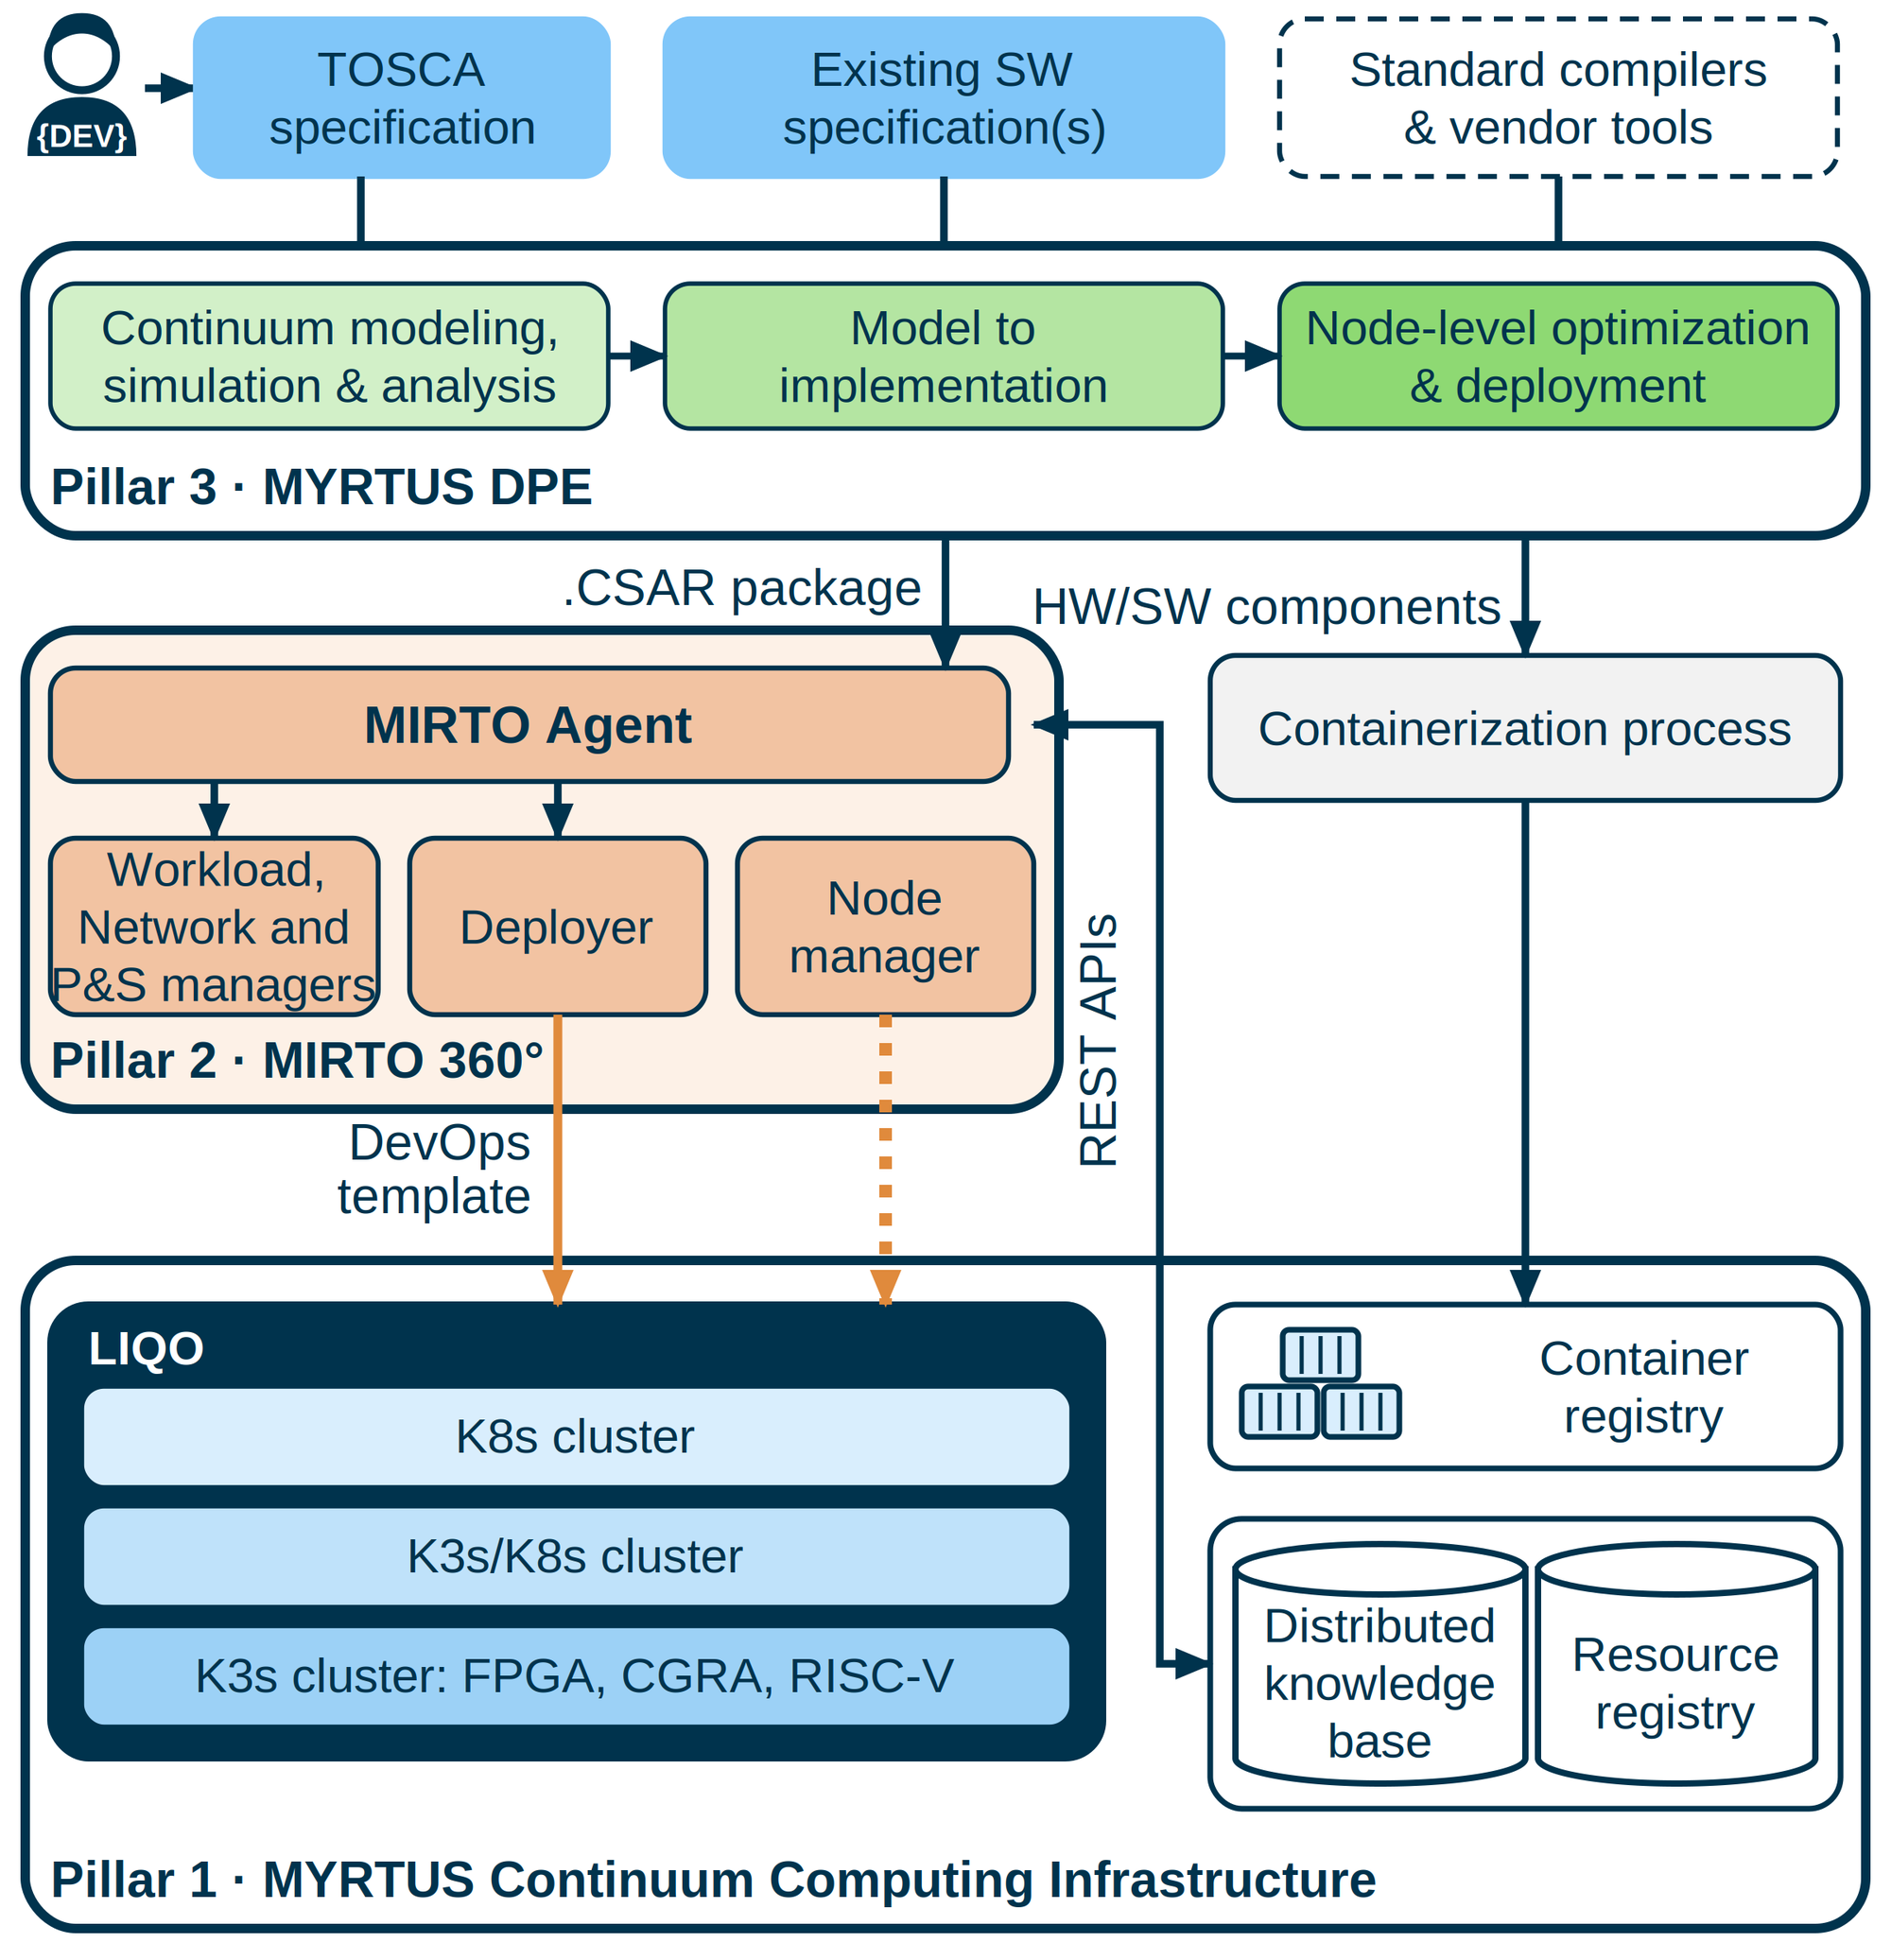
MYRTUS technology results are organised around three pillars that together form a chain from application design to execution. Pillar 1 provides the edge-fog-cloud reference infrastructure on which applications run. Pillar 2 provides MIRTO, the cognitive engine that orchestrates workloads across this infrastructure, deciding where and how each workload is placed and executed. Pillar 3 provides the Design and Programming Environment (DPE), the methodology and toolchain through which applications are developed, optimised and packaged for deployment.
See how the three pillars work together in Concept and Methodologies →
MYRTUS Pillar 2
To achieve flexibility and overcome the current silos-like management of services, MYRTUS provides the MIRTO cognitive engine. MIRTO pushes runtime adaptivity between and across layers. Resources are continuously monitored, and runtime orchestration adapts the placement of workloads to achieve high performance and energy efficiency, preserving security and trust. AI-based and distributed strategies, including swarm intelligence, distributed constraint optimisation, deep reinforcement learning and federated learning, are used to optimise loads and make the most of the available continuum.
MIRTO cognitive engine is responsible for high-level continuum orchestration both at deployment time (when a computation request is issued) and at execution time (while tasks are already running). This dynamic orchestration entails four steps executed in loops:
1. sensing of internal and external triggers for the orchestration;
2. evaluation of aggregated local and global information;
3. decision for resource allocation/configuration to improve KPIs;
4. reconfiguration/reallocation.
Four primary drivers for optimization are there: optimal workload execution (e.g. improving throughput and/or latency), optimal network usage (e.g. reducing network congestion, while guaranteeing adequate computing power), optimal node configuration (e.g. trading-off QoS to minimize energy consumption in specific components), and privacy and security guarantees (e.g. changing the adopted set of components according to the requirements of a newly incoming task).
Since these drivers often pull in different directions, orchestration is a multi-objective problem. Rather than simply looking for the fastest or least energy-consuming node, MIRTO searches for a configuration that satisfies all functional and non-functional requirements at once, and revises it whenever the environment changes.
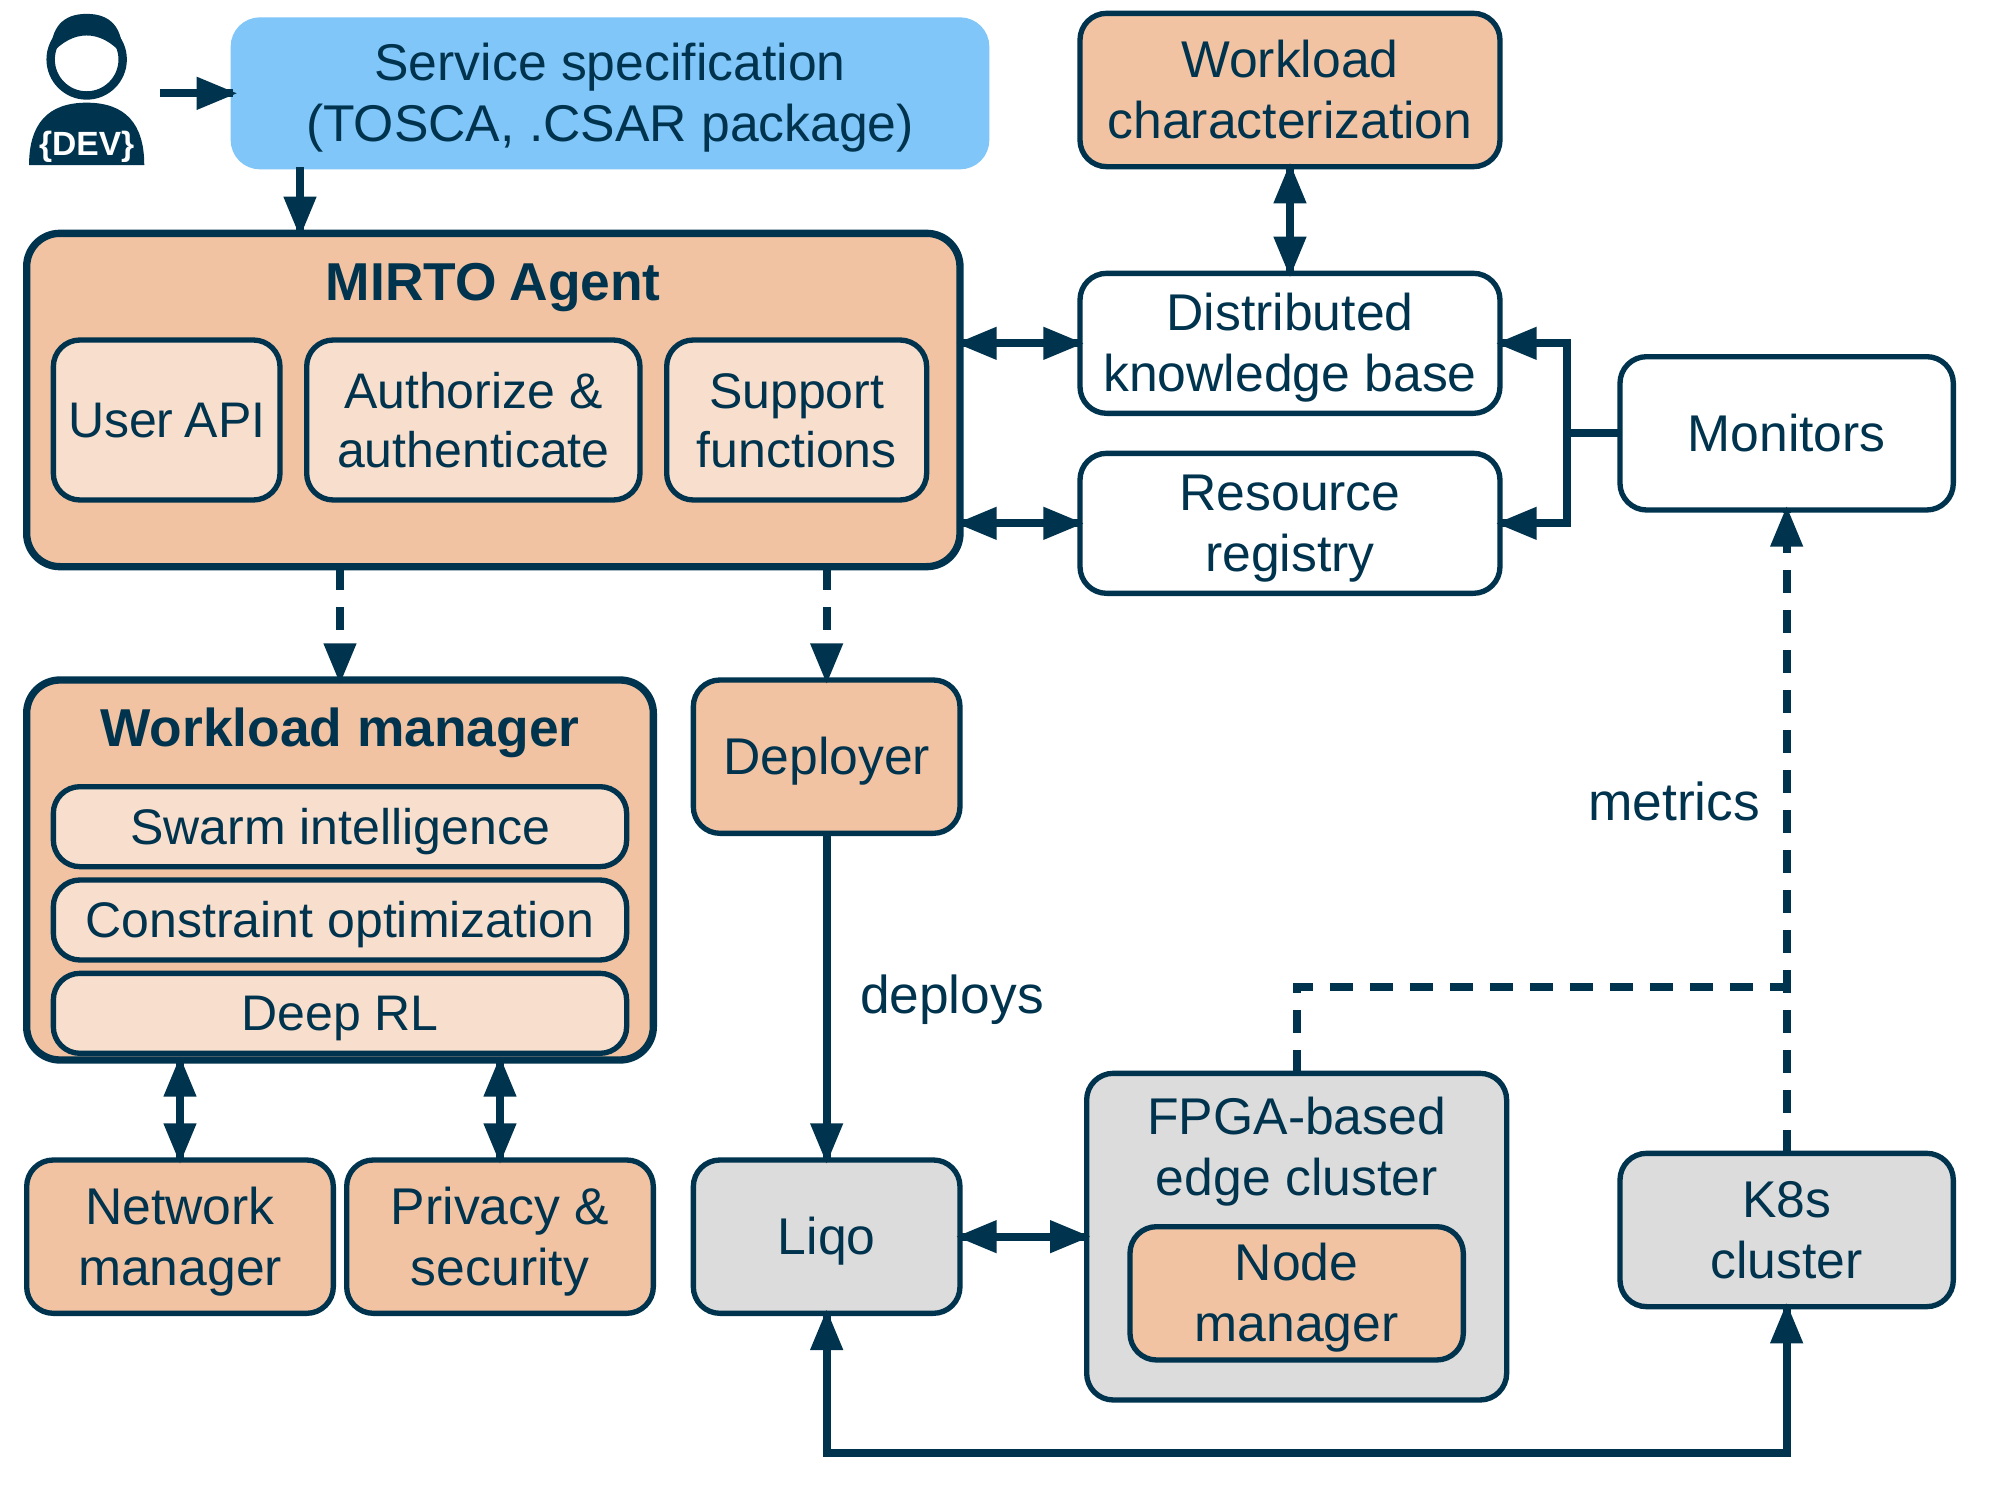
MIRTO cognitive engine architecture.
MIRTO is not a single monolithic service, but a set of modular components that communicate through well-defined REST interfaces, so that each of them can be replaced or extended without affecting the others. The MIRTO Agent is the entry point: it receives the application description as a TOSCA model prepared with the DPE, validates it and turns it into a service chain. Using the current state of the infrastructure, available through the Distributed Knowledge Base and the Resource Registry, the Workload Manager computes an allocation map, supported by the Network Manager and the Privacy and Security Manager. The Deployer then deploys the software components over the Kubernetes clusters federated by Liqo, from the cloud down to FPGA-based edge nodes, where the Node Manager takes care of local optimisation. Monitors keep the knowledge base up to date, closing the loop: MIRTO checks whether the application still behaves as intended and reallocates it when conditions change. All interfaces are defined in an implementation-agnostic and target-independent manner.
This complete flow, from the submission of a TOSCA specification to the allocation, the deployment and a new allocation after a change in the workload, has been demonstrated with the integrated MIRTO components.
Inside MIRTO
MIRTO is made of an agent and a set of managers and supporting services, each addressing one part of the orchestration problem.
MIRTO Agent and Deployer
The MIRTO Agent coordinates all managers and is the access point to start, update and stop applications. It accepts TOSCA specifications, and its information model, inspired by TOSCA, describes service chains, alternative software implementations, compute nodes, networks and their status. Once an allocation is decided, the Deployer applies it on the federated Kubernetes clusters through Liqo. Agents can be deployed in centralized, layer-centric or redundant configurations.
Workload Manager
The core decision-maker of MIRTO: it decides which implementation of each service to use and on which compute node to run it. Three interchangeable implementations share the same interface, so the most suitable strategy can be chosen for each context.
Swarm-based
Inspired by ant colonies, it runs one manager on every node: nodes that succeed in hosting workloads attract more of them, with no central controller. Scalable and robust to failures, it can also redirect service chains between edge, fog and cloud clusters.
DCOP-based
It models allocation as a distributed constraint optimization problem, solved with the SAM toolbox, and uses DynAA simulations to estimate the effect of each choice. Besides deciding where a service runs, it can choose among alternative implementations of the same service.
DRL-based
It uses deep reinforcement learning policies, trained offline, to decide whether each service runs on its edge node or is offloaded to the fog, and coordinates with the Network Manager for the bandwidth the offloaded services need.
Node Manager
It manages heterogeneous edge nodes that combine a CPU with FPGA-based accelerators, such as CGRAs, RISC-V processors and custom accelerators. Machine learning models, updated while the workload runs, predict power and performance: a scheduler uses them to decide which accelerated tasks run together, avoiding conflicts on shared resources, and an energy manager selects CPU frequency, active cores and FPGA offloading. Decisions are taken locally, without network delays. These nodes run the Edge OS, a lightweight Linux distribution that brings Kubernetes to FPGA-based devices.
Network Manager
It allocates the available uplink and downlink bandwidth among the communication flows requested by the Workload Manager, using pre-trained deep reinforcement learning models. For each flow it estimates the transmission latency and checks it against the latency requirement, so that placement decisions take communication into account.
Privacy and Security Manager
It makes security a driver of orchestration. It recommends the nodes able to meet the required security level, also considering trust and Gaia-X restrictions, and at run time changes the primitives used by the security and privacy proxies attached to each node, without stopping the application. It also aggregates a trust score for each node and supports homomorphic encryption for privacy-preserving computing.
Workload characterization
It describes how workloads actually use resources, to support orchestration decisions, trigger reallocations and train learning-based models. Complementary approaches look at the application and its services, at containers observed at deployment time without access to their source code, and at FPGA-based platforms, where nodes share their models through federated learning without moving the monitoring data.